AI multiplied what a content team produces; nobody multiplied the review. The bottleneck moved from creating to approving.
This weekend I took part in the 30X Hackathon and, in about 48 hours, built Gatekeeper Editorial 30X: an AI editorial filter that decides, in milliseconds, whether each piece of a brand’s content goes out, gets improved by AI, goes to a person for review, or gets discarded. And if it doesn’t pass, the AI fixes it on its own and checks it again.
Here’s the problem, how it works, the numbers, and what went wrong along the way.
The problem: an editor’s day #
Picture the editor of a content team today:
- They review dozens of pieces by hand, one by one: posts, scripts, clips, newsletters, screenshots. Many of them already made with AI.
- Everyone applies their own judgment, there’s rework, and there’s always the fear that something risky goes out to hundreds of thousands of followers.
Why not run everything through ChatGPT? Because a language model writes text you then have to interpret. It doesn’t give you a consistent, measurable “yes or no” for thousands of pieces a day.
The challenge, and why I picked this idea #
The hackathon had a challenge called “Reto 30X: JEV”, with this question: Which of 30X’s decisions could JEV make thousands of times a day, in milliseconds, and what does that look like working?
- 30X is a Latin American business school with a lot of social content: about 425,000 followers on Instagram.
- JEV is TypeSafe’s decision model. It doesn’t write text: it decides. It answers questions with typed answers and probabilities (pick an option, yes or no with a probability, or a score), fast and cheap.
Before writing code, I did my homework: I read the challenge and JEV’s documentation, looked at 30X’s website, Instagram and programs, and listed ideas that met three conditions: a decision repeated thousands of times a day, that can be measured, and that scales.
My teammate, Haron Acosta, proposed several ideas, including segmenting event sign-ups. I chose to start with the content “gatekeeper” because it’s understood in 10 seconds in a demo, it hits a real pain for any marketing team, and the same engine can later serve other decisions.
The principle behind the whole design:
JEV decides, the code calculates, generative AI only writes when needed, and a person only reviews what matters.
In practice, that means counting, adding, comparing against thresholds and handling dates live in regular code, never inside a question to the AI. And thresholds and editorial rules are data, not code: the Media team can adjust them without programming.
How it works #
Does this piece go out? #
- A piece comes in: text or an image screenshot, uploaded by someone on the team or generated by an AI.
- JEV answers 12 questions in a single call, built from the brand profile: topic and format; relevance, whether it’s actionable and its potential reach; and a set of yes/no answers with probabilities (too promotional, exaggerated promises, unsourced data, brand risk, sells something the brand doesn’t sell, spam, fit with the editorial line). JEV also “reads” images: it judges screenshots, not just text.
- The code applies the policy and picks a route. There are four outcomes:
- Approved: it goes out on its own. It needs high confidence, no flags and a good editorial score.
- Improve with AI: the gray zone.
- Review: real risk or doubt; a person decides.
- Discarded: spam or off-brand.
- If it doesn’t pass, the AI fixes it on its own, with no clicks. An OpenAI model rewrites the text in the brand’s voice, fixing only what JEV flagged. Another one generates a new, natural image, with real people and settings and the headline in the brand’s colors.
- JEV checks the new version again. If it approves, one click on “Approve and save” stores it as version 2, with its history.
- It gets published from a kanban board (To review, To improve, Approved, Rejected). In the demo, publishing is simulated; the real social media integration is a next step.
One important detail: if JEV doesn’t respond, a piece is never approved on its own. When the system gets it wrong, it errs on the side of caution.
The diet pills case #
This happened in production on delivery day. I uploaded a spam screenshot: “Pills to lose 10 kilos in a week, guaranteed results”.
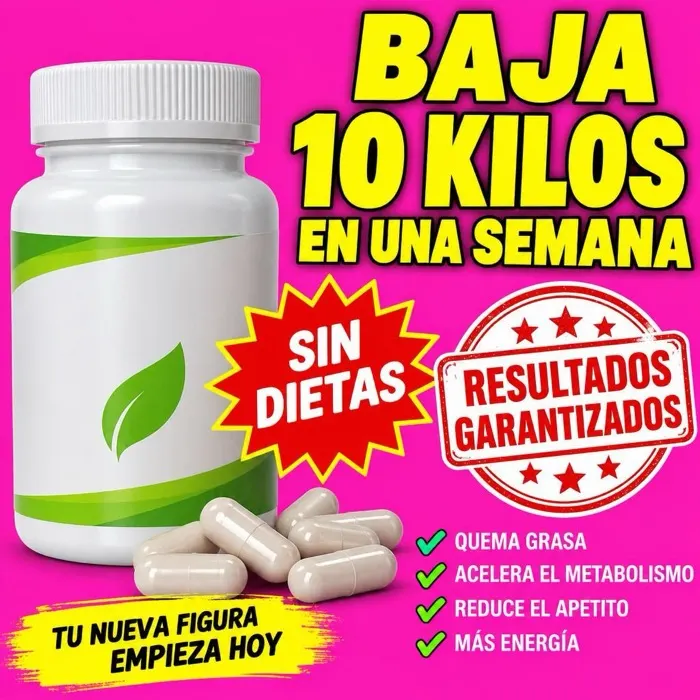
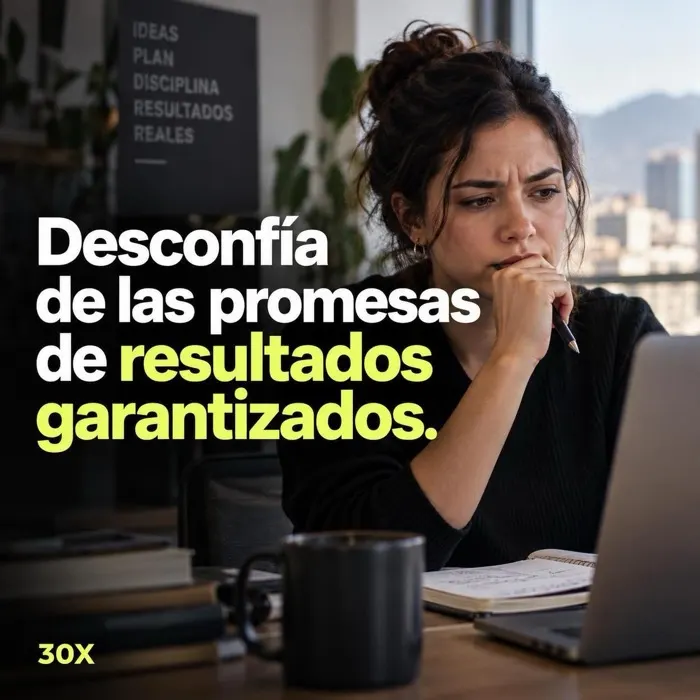
- JEV discarded it in under a second and said why: exaggerated promises, sells something 30X doesn’t sell, and unsourced health claims.
- The AI turned it, on its own, into a 30X post, “Be wary of promises of guaranteed results”, about keeping your judgment in the face of exaggerated marketing, with a new photo.
- JEV checked the new version and approved it.
The second decision: which program fits this sign-up? #
This was the number one idea 30X suggested: for every person who signs up for their events on Luma, which program fits them, and should we call them now? Today that’s also decided by hand.
It’s the same engine with a different decision. JEV reads only what the person enters when signing up (role, country, pain point, goal and topics), never 30X’s internal tags, and in one pass decides five things: the program that fits (or “no clear program”), their role, their AI maturity, whether they’re ready to talk to an advisor, and whether there’s enough context to decide. Then the code picks the action: hand them to an advisor, send the proposal, nurture them with free classes, or send them to human review.
For any brand #
During onboarding you paste your brand’s website and the system reads it: what it sells, who it talks to, how it talks and its colors. That’s used to build the questions JEV answers, including what that brand must never publish. Each account has its own brand profile, so it’s multi-brand from day one.
The numbers #
Scale #
This was the direct answer to the challenge. I ran 1,000 real decisions against JEV in production, with no cache:
| Metric | Result |
|---|---|
| Total time | 4.5 seconds |
| Decisions per second | 222 |
| Time per decision (p50) | 128 ms |
| Decisions under 250 ms | 95% |
| Times the OpenAI fallback was needed | 0 |
At that rate, 10,000 pieces in a day get reviewed in under a minute. The team never waits for the filter. The test can be rerun live from the app, under Results.
Content quality #
I built a test set of 45 simulated pieces, hand-labelled with what should happen to each one:
| Metric | Result |
|---|---|
| Accuracy with the first policy | 53% |
| Accuracy after calibration | 80–87%, depending on the run |
| Pieces resolved without a person touching them | 42% |
| Risky or spam pieces approved on their own | 0 |
| Time per piece, even with an image | ~0.3 s |
In hours, that’s about 3.5 hours saved per 100 pieces, counting 5 minutes per manual review (an adjustable assumption).
Sign-up segmentation #
On 200 of the 697 anonymous profiles 30X shared:
| Metric | Result |
|---|---|
| Match with the program 30X suggests | 55.5% |
| Match where 30X did suggest a program | 60% |
| Match for AI Sales | 95% |
| Precision when flagging “ready for an advisor” | 88% |
| Time per person | 93 ms |
An honest reading of the 55%: it’s a first iteration on very sparse profiles (73% don’t state their role). What already works is that the advisor knows who to call first.
How I built it #
Stack: Next.js 16 with React 19, TypeScript and Tailwind v4. TypeSafe’s JEV through its SDK, with OpenAI’s decisions API as a fallback if JEV fails (it was used zero times in the measurements). OpenAI models to rewrite text, extract the brand from its website, and generate images. SQLite on a persistent volume. Docker and Coolify on my own server, with automatic deploys on every merge and DNS on Cloudflare. CI on GitHub Actions running lint, typecheck, tests and build.
Architecture: one module per business area (content review, brand, accounts, workspace, segmentation), each with its pure domain, use cases, adapters and UI. API routes are thin, every call to JEV goes through a single client, secrets stay on the server, and the Strict, Balanced and Flexible policies are data the team changes without a deploy.
Around the engine, a lightweight CRM: email-only accounts, an inbox with what needs a person, the kanban with history and versions, loading a content grid from Excel or CSV with a campaign calendar, buttons to copy or download, the Results screen, and daily usage limits so nobody abuses the API keys of a public demo. The Excel part came from a feedback session: teams still plan there, so the system adapts to that instead of asking them to change.
How I worked: I used AI coding agents (Claude Code) as a team. Several worked in parallel, each on its own branch, while I reviewed, decided and merged. With Conventional Commits and small PRs, that was more than 40 PRs over the weekend, each with green CI before going in, and after every merge I deployed and checked in production. Before recording the demo, an agent rehearsed the whole script against production and found real problems we fixed in time.
What went wrong #
- The system said “adds little value” too often. The question only measured whether a piece was a “how-to”. I changed it to measure any contribution: a fact, a story, event information or a clear next step.
- Event announcements were flagged as hard selling. I adjusted the questions: inviting people to an event or a free class isn’t selling, and a brand’s own data isn’t “unsourced data”.
- Regenerated images came out flat and orange. They were lifeless text cards, and the default brand color was wrong. I rewrote the image prompt based on 30X’s real feed: photos with people and settings, bold headline in the brand’s lime.
- When reading Instagram and LinkedIn, the system described Instagram and LinkedIn instead of the brand. When the profile was blocked, it fell back to the social network’s home page. I fixed it by detecting social networks and reading only their preview.
- A version approved by JEV switched to “to improve” when saved. Saving triggered a new review and, since it was right at the confidence threshold, it sometimes changed route. Now it’s saved with the same verdict the person saw. The automated script rehearsal caught this bug hours before delivery.
- The deploy healthcheck failed because
localhostresolved to IPv6 inside the container. Using127.0.0.1fixed it. - An AI-generated sample image included a copyrighted character. I regenerated it and added a rule to the prompt: no characters, logos or real people.
Product decisions #
- From a technical dashboard to an app for the team. The first design showed latencies, probabilities and costs. I simplified it to what the team needs to see: what goes out, what doesn’t, and why. And many tabs became five sections: Inbox, Content, Create, Sign-ups and Results.
- What was fastest for the demo was also best for the user. The AI fix starts on its own when a piece is uploaded, with no button, and approved content is published in one click.
- We stopped talking about money and talked about people. A mentor told us JEV’s low cost is obvious and that we should focus on how it helps teams. We went from “it costs cents” to “your team stops approving by hand and gets back to creating”.
- Honesty with the numbers. We also showed what isn’t good yet, like the 55% in segmentation, and explained why.
What I learned #
Decision models change how you design with AI. Instead of asking a language model for its “opinion” and then interpreting its text, you ask small, typed questions and the code decides with clear rules. It’s faster, measurable and easy to audit.
Separate deciding from writing. JEV decides; the language model only writes when needed; the person reviews what matters.
Calibrate with labelled data. Going from 53% to 80–87% accuracy wasn’t about switching models: it was about adjusting the questions and thresholds with examples.
AI agents speed things up enormously, but product judgment, decisions and verification are still the human’s job.
The same engine works for the next decision: who’s about to drop out of a program, or whether an AI agent’s reply can go out to a customer. It’s another set of questions, not another system.
Links #
- Demo
- Pitch
- Playbook
- Open source on GitHub (AGPL-3.0)
Team DevGain: Michael Liendo (product, architecture, backend, AI and deployment) and Haron Acosta (full stack: the landing page, the sign-in screen and early ideas).
Does your team review content by hand? #
If someone at your company spends the day approving pieces one by one, let’s talk. Message me on WhatsApp and tell me how you handle it today.